Apparently Grok 4.7 has 40% more weights than Grok 4.6, but the price ($6 output token, $2 input) is the same.
Given that the decrease in their margin and the fact they delayed the release of Grok 4.7 almost two weeks past the original date, XAI must not have been happy with the results for 4.7. And XAI also waited the day before Opus 5.5 is rumored to launch. I imagine Opus 5.5 will blow Grok 4.7 out of the water benchmark wise.
However, I have become skeptical of benchmarks. Grok 4.5 solved some issues setting up a buildroot system that Fable 5 couldn't do. I find the post cursor groks are phenomenal at frontend web development, though Claude is much better at backend ruby.
My favorite part of the new Groks has been how they speak in plain english. I simply cannot stand Claudish. Or even GPT, which doesn't have Claude's ticks but definitely likes to handwave explaining technical concepts. Still, nothing beats Claude 3.5 and 4 with explaining since it seems all models have regressed. I wonder if Grok 4.7 will also regress with English because of all the RL.
vessenestoday at 4:47 PM
Nice to see this release cadence increasing and some continued improvement in quality. I am guessing these models are basically still outcomes of the cursor team integrating with the massive amount of compute they now own: I’d imagine we will see significant step up improvements with grok 5 later this year as the team gets more experienced and confident with larger training deployments. Here’s hoping for another competitive frontier model!
nicolamanzinitoday at 8:31 PM
[dead]
saejoxtoday at 5:12 PM
Not even close to astra. Astra is something else. It is expensive, but uses way fewer tokens do my tasks.
xAI missed its chance, Ball is on Anthropic's court.
For some reason reasoning effort low and medium used similar numbers of tokens, and xhigh used less than high. I think I need to try without OpenRouter in the middle.
UPDATE: I tried again with the xAI API directly: https://tools.simonwillison.net/markdown-svg-renderer?url=ht... - not a great deal of difference between reasoning levels, and this time xhigh and low used the same number of reasoning tokens for some reason.
Additional prompt instructions: "Add scrolling clouds behind the statues. Dynamically light the statues based on mouse position. Use diffui to generate the normal maps/depth maps/roughness maps of the objects, and to separate out the assets on to different layers."
Overall I find these models are getting good at following image as a source of instructions, but their refinement of the output varies heavily between the models. Astra's final output feels more polished, has better visual contrast, and the animations between the pages are smoother. Grok also chose to light all of the background elements, which imo overcooks it a bit.
Still though, for the price it's a great starting point.
johnfaheytoday at 5:38 PM
No doubt xAI has seen rapid progress, but it's been several months of them being "just behind" OpenAI and Anthropic. It seems the gap between just behind the frontier and pushing it is a lot wider than most people thought it was a year ago, and that's why a clear third contender in the frontier model space has yet to materialize.
trentortoday at 5:56 PM
Looks like they have still problems with caching. Prize is double the other providers for cache hits... which is most of what I do. :/
qwerpytoday at 5:51 PM
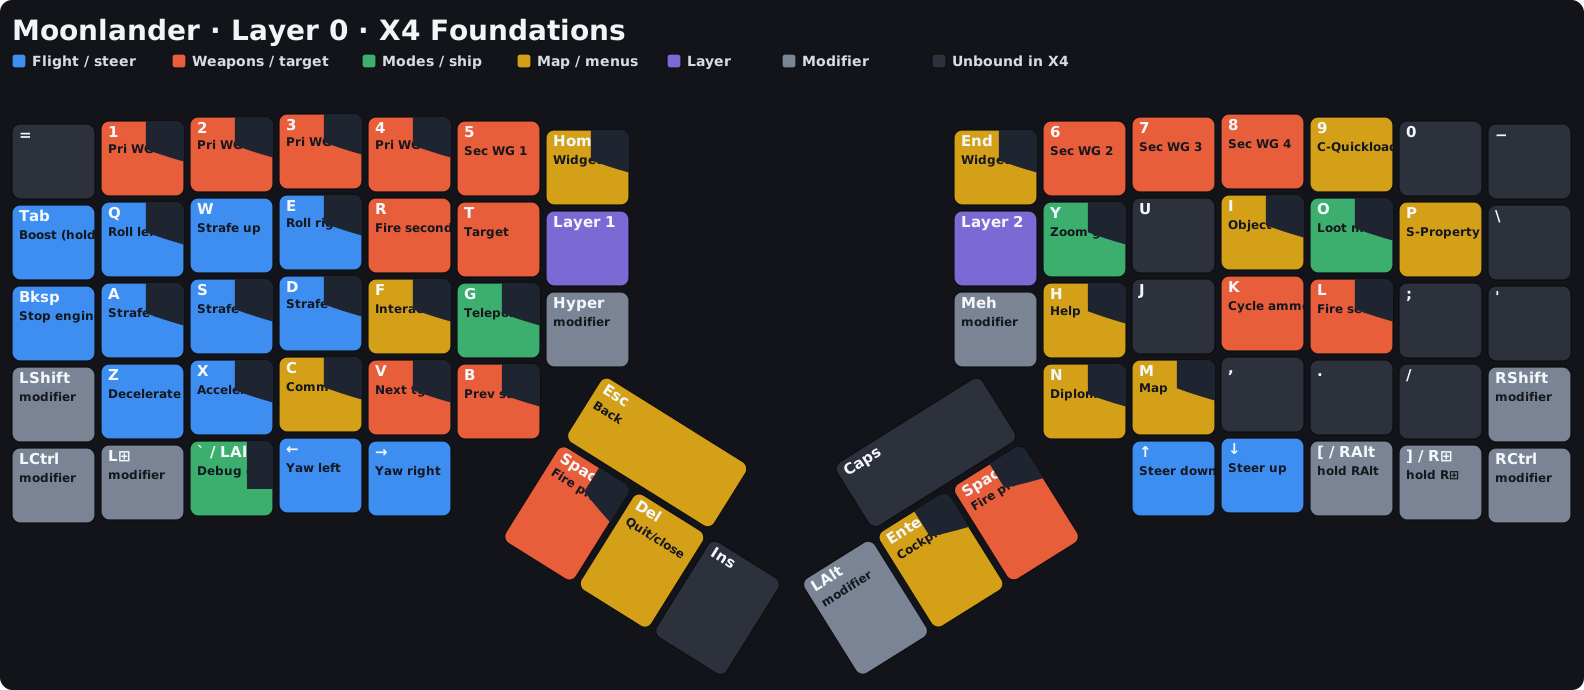
I've been using 4.6 for some one-off game mods/utilities and it has done very well. "I have a very niche keyboard (Moonlander) and I play this very niche space sim, make me a SVG keyboard cheatsheet for it". Told me to grab keymap.c for the keyboard and inputmap.xml for the game's key bindings, churned for a while, then spit out a pretty good first attempt, along with the python script used to generate it. Spent another hour of back and forth to refine the script, and now it generates great diagrams that will adapt as my keyboard firmware and game bindings evolve: https://files.catbox.moe/x0u76x.svg
Excited to try 4.7. I hope they fixed the "it's not X, it's Y" that showed up in 4.6.
maz1btoday at 4:52 PM
Either way, the fact that xAI or SpaceXAI or whatever the name is, I can commend the team behind it on their rapid ascent and progress by being close and or on the frontier in several respects.
WarmWashtoday at 5:07 PM
Good thing they used 5.6 sol instead of Astra for benchmarks, the EEbench one is crazy[1]
Significant regression in token efficiency compared to Grok 4.6 suggested by artificialanalysis.ai Intelligence Index Comparisons.
GodelNumberingtoday at 5:50 PM
Every Grok release obscures their cache pricing while highlighting their input/output pricing
From their headline comparison:
  Grok: $2/$6 per million

  Fable: $10/$50 per million


  What this doesn't say: Grok costs 0.50/M cache read, Fable $0.25/M cache read
Long running agentic workflows are dominated by cache reads.
Just makes Grok sound deceptive, and more importantly, reliant on user's lack of understanding of costs aka predatory (which in turn is more infuriating)
gslepaktoday at 5:41 PM
Does anyone have any experience with Grok's subscription? How does it compare price-wise to the API?
shdtabasumtoday at 5:39 PM
Why Chinese models from Kimi, Deepseek are not added in comparison benchmarks?
swalshtoday at 5:35 PM
Codex has become my goto tooling. I used to be a Claude Max subscriber, but I was becoming disappointed with the quality of the output from Opus 5. Fable chewed through my usage too quickly to be practical. Moving to a Pro account w/ Codex was a big improvement. Sol had great output, and the usage was more than sufficient for most of my needs. However astra does tend to chew up usage, so when i've done to much of that, and it's became an issue Grok Build has beocme my second go to account. The output especially after the cursor purhcase has become quite good, and the usage has always been very generous.
ls1911today at 4:02 PM
after using cursor grok & trae.ai for several months , grok curor is highly superior results to trae.ai
BoumTACtoday at 6:01 PM
Vals AI just affirm that Grok 4.7 is worse than Grok 4.6 (It ranks #24 on the Vals Index at 54.2%, down 5.0 points from Grok 4.6 (#14, 59.2%))
After mechahitler and understanding how it got to that point I am embarrassed for anyone who pays attention to or uses Grok. Do better.
6thbittoday at 4:54 PM
( why is the x-axis on the first chart in descending order ? )
c0rruptbytestoday at 5:47 PM
as someone who is limited by amazon bedrock support at work (no idea why we got stuck with the worst one) - grok is literally the only budget-ish model option, so nice to see it updated, Sol and Opus are just too rich for my blood. Luna is good but so slow at getting things done (tps wise it's fast)
simonwtoday at 5:05 PM
$2/million inout and $6/million output but I couldn't see any pricing information for cached input tokens?
oh_notoday at 7:01 PM
the AA numbers are generationally bad. double token use (the one thing Grok was good at was low reasoning usage!) to gain 5% in the benchmark score. with reportedly a larger model. maybe it shows gains IRL but wow, I've never seen a new generation model look so underwhelming compared to the last.
sourcecodeplztoday at 6:45 PM
looks like token efficient/verbosity took a big hit.
Did 4.6 not have an x-high reasoning level? Why are they comparing 4.7 x-high with 4.6 high?
sidgtmtoday at 4:36 PM
In my experience Grok especially inside Grok build is pretty solid choice, it’s a no nonsense model and stays on its course. Another surface where I truly enjoy the experience of using Grok model is Grok bot
alansabertoday at 7:20 PM
As anthropic/openai subscription allocations get squeezed you'll see more people using "second rate" closed models like grok. The token allowance with a Cursor subscription is crazy.
andsoitistoday at 4:51 PM
Congratulations to the team!
Invictus0today at 7:37 PM
SpaceX AI releasing "Grok" has to be some of the worst branding I've seen in my lifetime
inshardtoday at 7:27 PM
Any real world experience with Grok Ultra $300 monthly subscription vs Claude Code Max in terms of overall built work mileage, or general token limits?
deletedtoday at 5:59 PM
MuffinFlavoredtoday at 5:07 PM
If the CursorBench 4.0 score diagram is the headline, I read it as "Grok 4.7 xHigh is almost the same as Fable5.1 on low".
Is there a metric for like... time taken when comparing these two? I see score and cost.
If Fable5.1 can knock it out more quickly on low but Grok4.7 might take twice as long to stumble through a problem (and leave behind a bunch of yucky comments or un-needed extra unit tests), are they really comparable?
Or like... the "quality" of the solution? "It works" versus "it's unmaintainable/very messy/hacky".
gaigalastoday at 6:53 PM
Pacing the frontier, with an aggressive release cadence. Gotta love the US tech industry.
brcmthrowawaytoday at 6:34 PM
Dumb question. Are these products really winner-take-all? Why is there such a furious rate of development?
kristofferRtoday at 4:18 PM
What's with the deceptive graph on top? Not including Astra can't have been an oversight, did the model compare poorly to it?
Saline9515today at 4:50 PM
I tried in Omp (Oh-my-pi), and so far it's really problematic.
It will loop in thinking mode ("Let me implement those fixes: Fix 1, Fix 2, Fix 3 .... Fix 80, Fix 81"), ignore the AGENTS.md instructions, corrupt plan files, etc etc... I have 5.6 Sol as advisor/watchdog, and it blocks every turn, I never saw this. Quite a shame, 4.6 wasn't so bad.
simianwordstoday at 4:10 PM
I guess it’s only my opinion but having used grok for personal chat: it’s by far the worst one amongst Claude, ChatGPT and even Deepseek, Gemini etc.
The personality is bland and it doesn’t work nearly as hard or even tries to help.
mempkotoday at 7:25 PM
Until Musk owns up to his Nazi salute, I won't be using Grok, sorry. I don't care how good or cheap it is. And no, I won't stop talking about it either.
usumgallutoday at 6:59 PM
[dead]
deletedtoday at 5:26 PM
Tsarptoday at 4:50 PM
Waiting on simonw "Generate an SVG of a pelican riding a bicycle " benchmark to judge this model
I refuse to use Grok. Mostly because of the usual reasons - somehow this high profile AI model seems more disgusting than others and it is in a way impressive.
But also Xai doesn’t seem to care about user experience and long term support.
outside1234today at 7:42 PM
Who uses this trash?
dom96today at 5:17 PM
It’s a shame this model has such negative political baggage associated with it. It’s the only one I decided not to run in my LLM benchmarks[1].
Well I "tried it out" I asked it one question, and it gave no answer and said "Sign up to use more!" I don't think I'll be doing that, no.
I can't think of a single dimension grok is winning on (capability, cost, voice), but want to stay open-minded -- anybody want to vouch for its capabilities in any domain?